Machine Learning Models Refining Anomaly Detection Across Cross-Border Subscription Settlement Workflows
Dana Ludwig · Aug 14, 2026
Machine Learning Models Refining Anomaly Detection Across Cross-Border Subscription Settlement Workflows
Cross-border subscription settlement workflows handle recurring payments that span multiple currencies, regulatory frameworks and banking systems, and machine learning models now play a central role in spotting irregular activity within those flows. These models ingest transaction records, user behavior signals and settlement timestamps, then flag patterns that deviate from established norms. Observers note that such systems reduce false positives compared with rule-based approaches because they adapt to shifting volumes and seasonal variations in subscription services.
Core Components of Cross-Border Subscription Settlements
Subscription settlements across borders typically route funds through acquirers, card networks and local banks, each step introducing variables such as foreign exchange rates, compliance checks and time-zone delays. Data indicates that daily volumes in this segment reached several billion dollars by mid-2025, with growth concentrated in digital services and software-as-a-service platforms. Machine learning systems map these variables into feature sets that include merchant identifiers, customer location histories and prior charge success rates, allowing algorithms to score each transaction for risk before final settlement occurs.
Researchers have found that supervised learning models trained on labeled datasets of confirmed fraud cases achieve higher precision when they incorporate currency-pair volatility metrics alongside traditional velocity checks. Unsupervised techniques, meanwhile, cluster transactions that share unexpected combinations of attributes, such as rapid upgrades to premium tiers from new geographic regions. Both approaches operate on streaming data pipelines that update model weights nightly, ensuring detection logic remains aligned with emerging settlement patterns.
Model Architectures Applied to Anomaly Detection
Gradient-boosted decision trees and deep neural networks represent two architectures frequently deployed in production environments for this use case. The former excels at ranking feature importance, revealing that cross-border IP mismatches and mismatched billing addresses rank among the strongest predictors of anomalous settlements. Neural networks, by contrast, capture non-linear interactions across dozens of variables and have demonstrated recall rates above 92 percent on benchmark datasets released by industry consortia.
Ensemble methods combine outputs from multiple models, weighting each prediction according to recent performance on regional subsets of data. This technique proves useful when settlement rules differ sharply between jurisdictions, because separate sub-models can specialize in European Economic Area flows or Asia-Pacific corridors without forcing a single global threshold. Real-time scoring occurs within milliseconds of authorization requests, and flagged items route to manual review queues or automated holds depending on configured risk tolerances.
Integration with Existing Settlement Infrastructure
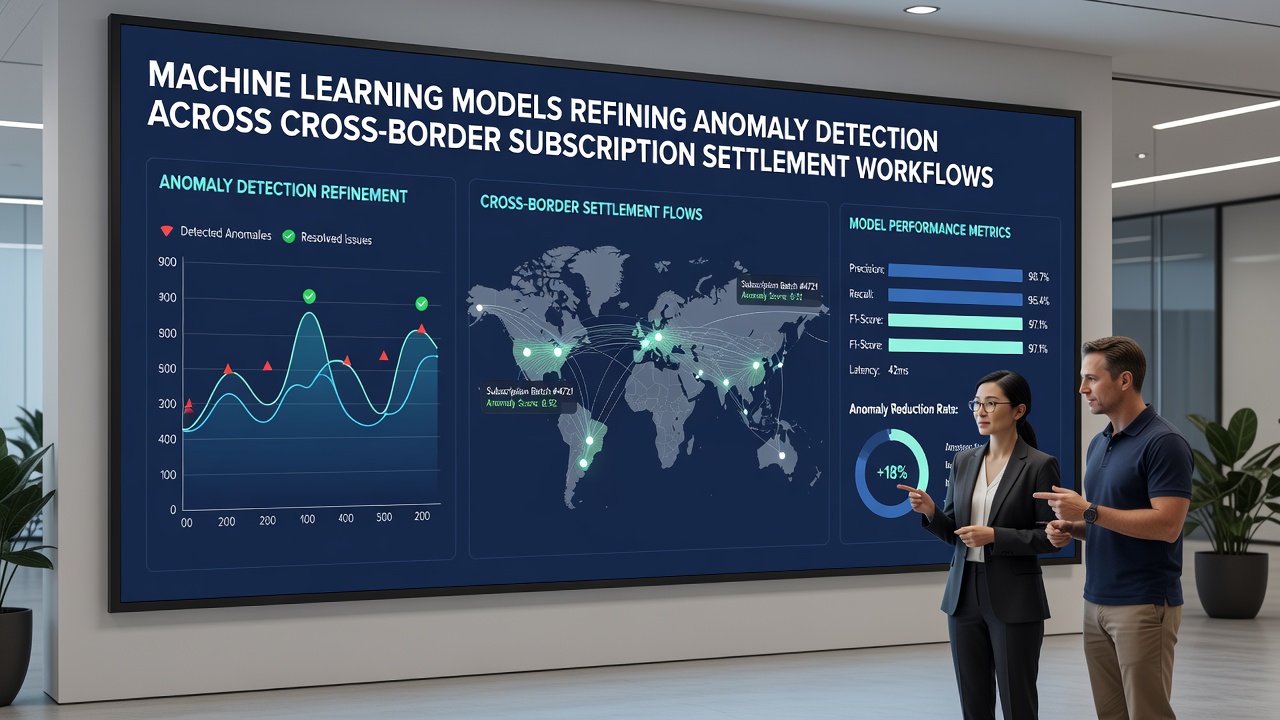
Payment processors integrate these models through API endpoints that receive transaction payloads and return risk scores before funds move between acquiring and issuing banks. According to Bank for International Settlements reports on cross-border payments, such integrations have lowered average settlement failure rates by approximately 18 percent in markets that adopted advanced analytics by 2025. The architecture typically layers a feature store that normalizes incoming data, a model inference service running on GPU clusters and a feedback loop that retrains on outcomes from dispute resolutions.
August 2026 marks the scheduled rollout of updated ISO 20022 messaging standards across several major clearing houses, and machine learning pipelines already incorporate the richer data fields these messages provide. Enhanced fields include purpose-of-payment codes and structured remittance information, which models use to distinguish legitimate subscription renewals from attempts to obscure fund origins. Observers note that organizations testing these enriched datasets report measurable gains in detection granularity for recurring cross-border charges.
Performance Metrics and Validation Practices
Validation studies track precision, recall and area under the ROC curve on hold-out sets that mirror live traffic distributions. Figures reveal that models retrained monthly maintain stable performance even when subscription cancellation rates fluctuate due to macroeconomic events. External audits compare model outputs against samples reviewed by compliance teams, confirming that anomaly scores correlate with actual dispute incidence at statistically significant levels. Industry groups such as the Payments Canada research program have published anonymized performance benchmarks that participants use to calibrate their internal thresholds.
Continuous monitoring dashboards surface drift indicators when feature distributions shift beyond predefined bounds, prompting data scientists to investigate root causes such as new market entries or changes in local tax collection rules. These practices ensure that detection remains effective as subscription ecosystems expand into additional regions.
Conclusion
Machine learning models continue to refine anomaly detection by processing richer datasets and adapting to regulatory updates in cross-border subscription settlements. Their deployment across settlement workflows supports more accurate identification of irregular activity while maintaining throughput required for high-volume recurring billing. Ongoing standardization efforts and expanded data fields further enhance model inputs, sustaining incremental gains in detection effectiveness.